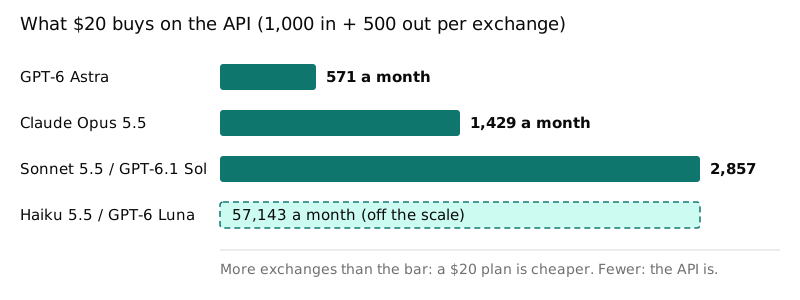LLM cost optimization

Increase your return on AI investments.

Every token should generate returns. We find where yours don't — and fix it.

AI spend is growing faster than the ability to see it.

79%

of companies had AI cost overruns in the past 12 months.

DoiT, 2026
26%

have full real-time visibility into their AI costs.

KPMG, 2026
$2.59T

worldwide AI spend in 2026, up 47% year on year.

Gartner

The numbers, October 2026.

Prices, models and trends we track for clients, checked against vendor pages. Each chart opens the full guide with sources.
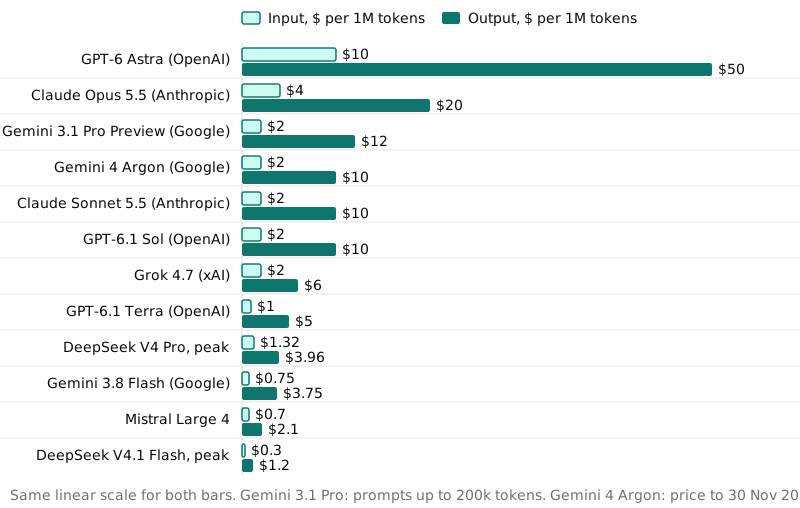
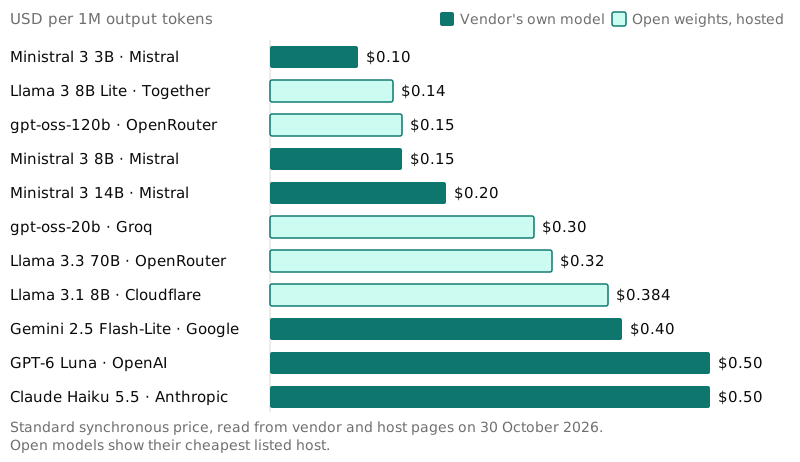
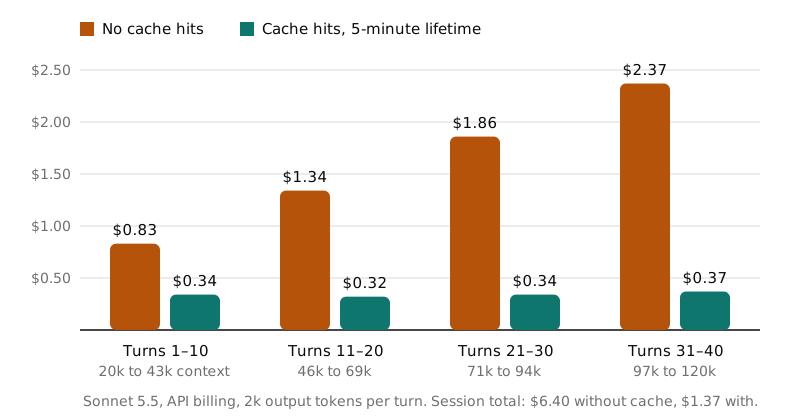
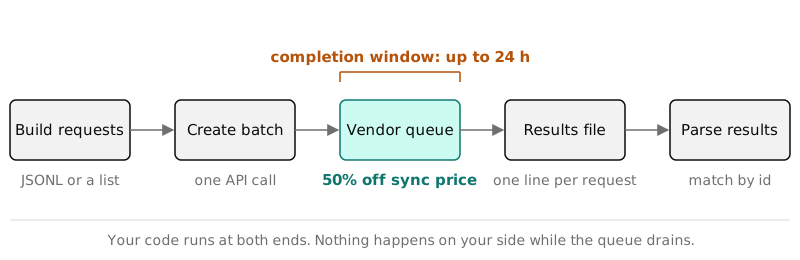
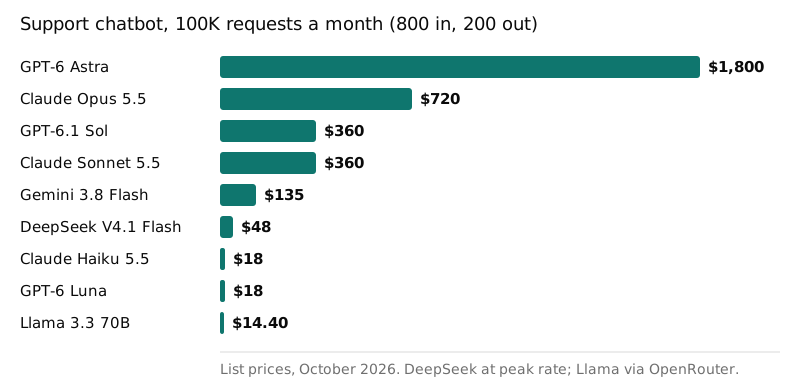
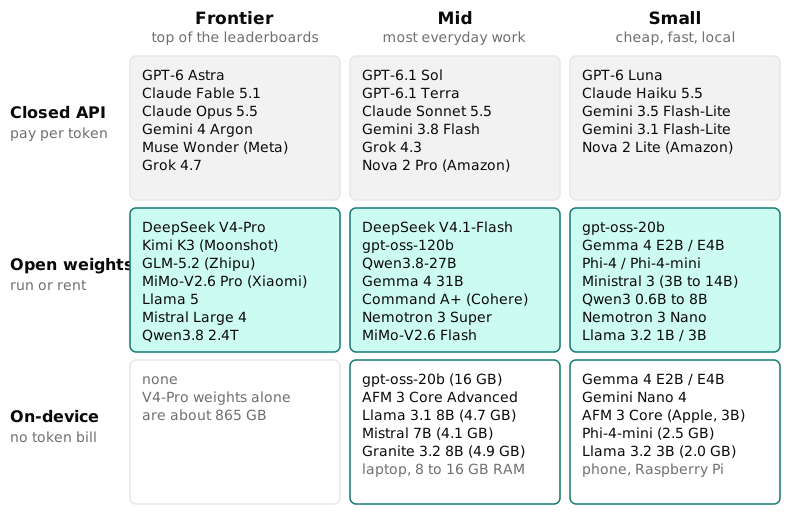
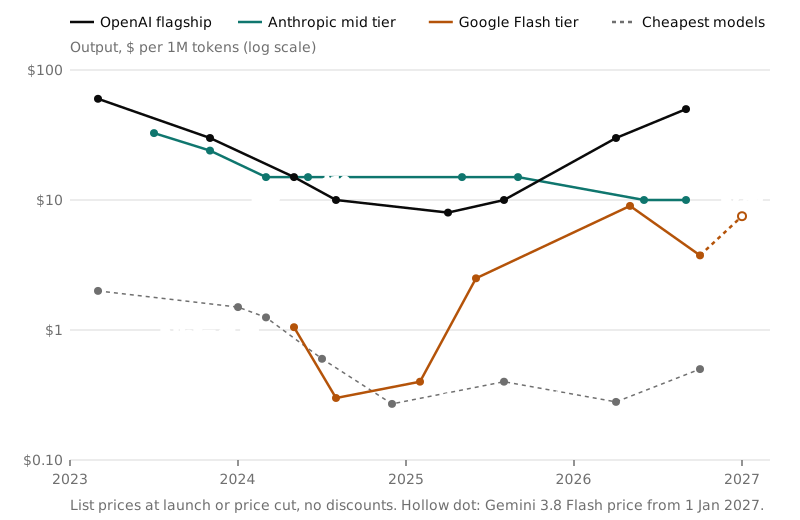
Input and output list price per million tokens for twelve widely used models, October 2026, sorted by output price. LLM API Pricing, October 2026: Cost per Million Tokens Input and output list price per million tokens for twelve widely used models, October 2026, sorted by output price. Capability tiers across, ways to get the model down, October 2026. Bracketed sizes are Q4 downloads from the Ollama library, except gpt-oss-20b, where 16 GB is the memory the AWS model card says it fits in. The AI Model Map 2026: Paid, Free, Large and Small Capability tiers across, ways to get the model down, October 2026. Bracketed sizes are Q4 downloads from the Ollama library, except gpt-oss-20b, where 16 GB is the memory the AWS model card says it fits in. Output price per 1M tokens at launch or price cut for three vendor lines and the cheapest models of each period, log scale. LLM Prices 2023–2026: How Far Inference Costs Have Fallen Output price per 1M tokens at launch or price cut for three vendor lines and the cheapest models of each period, log scale.
Three ways we turn AI spend into AI return.

Engagements start with an audit. Most teams see where the money goes within the first two weeks.

Start here

AI Cost Audit

We analyze your AI spend across every model, pipeline, and team — identify where budget leaks, which costs can't be attributed, and what to fix first.

Book an audit →
Optimize

AI Workflows Optimization

We redesign your LLM pipelines — model routing, prompt compression, caching, and agent guardrails — so you get the same output for meaningfully less spend.

Talk to us →
Govern

AI Cost Strategy

A long-term ROAI framework: cost attribution by product and team, governance policies, budget controls, and quarterly reviews as your AI usage scales.

Talk to us →

Guides

Long reads on what LLMs cost and how to spend less. Newest first.

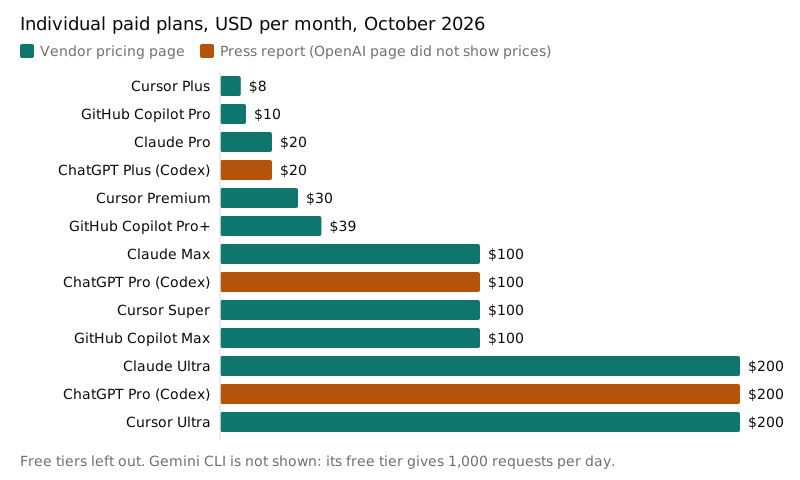
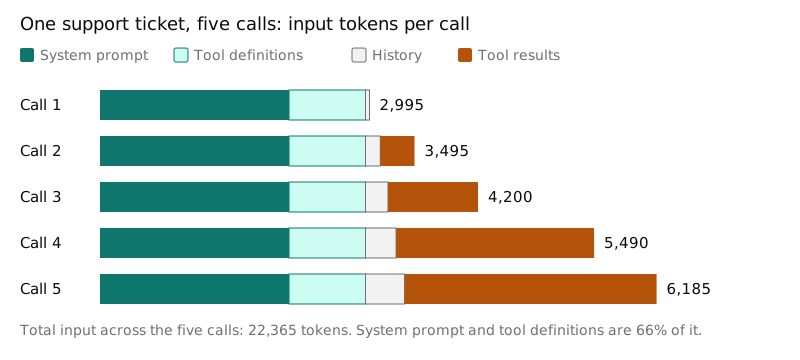
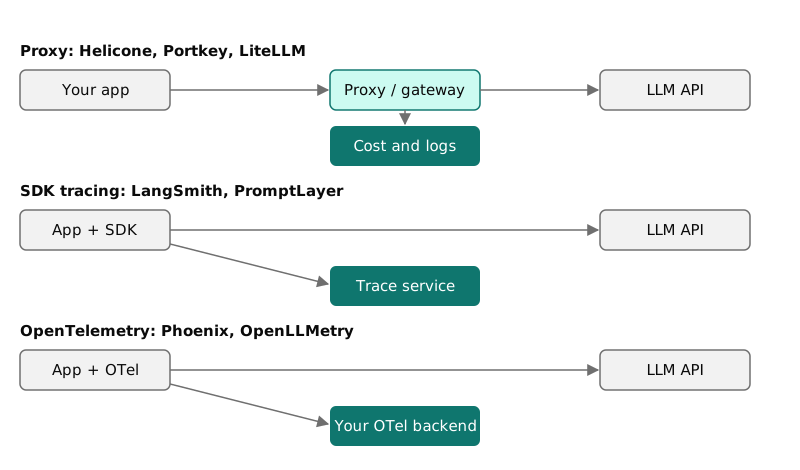
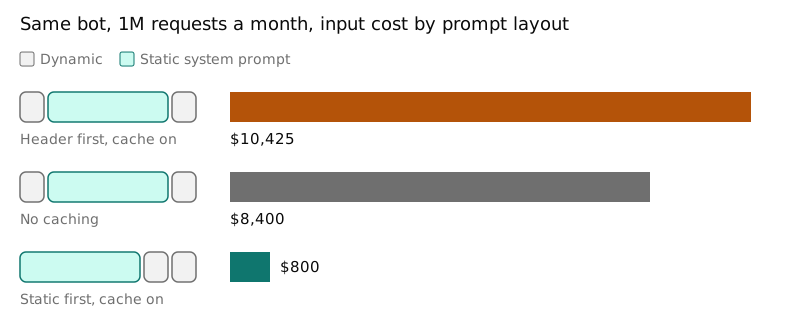
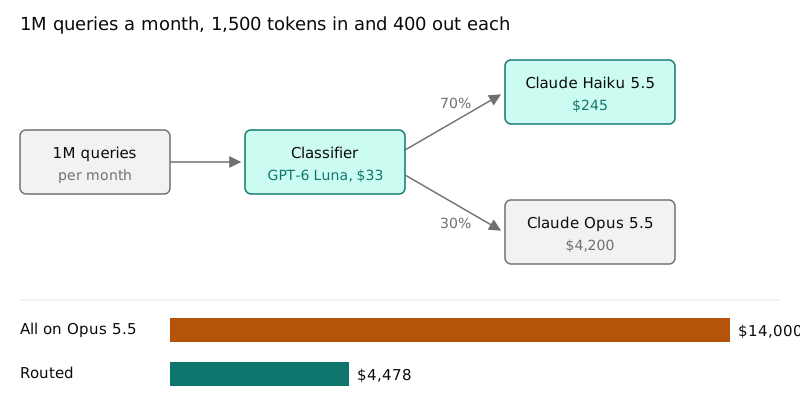
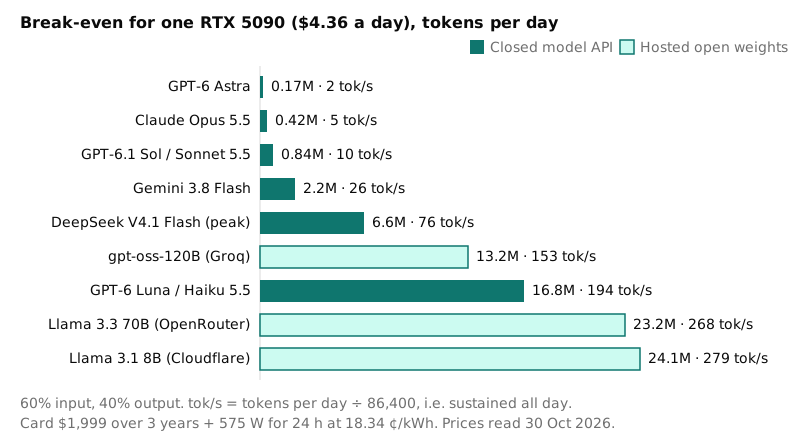
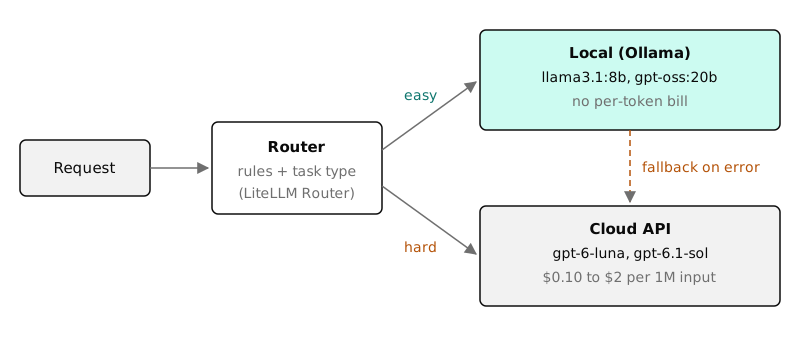
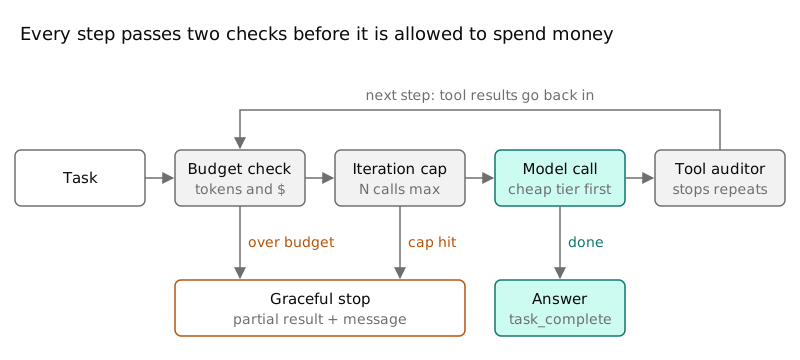
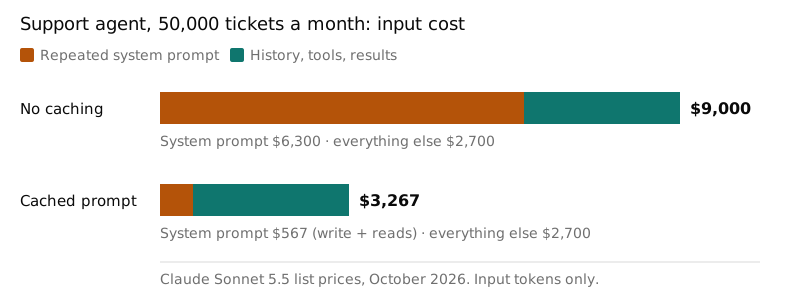
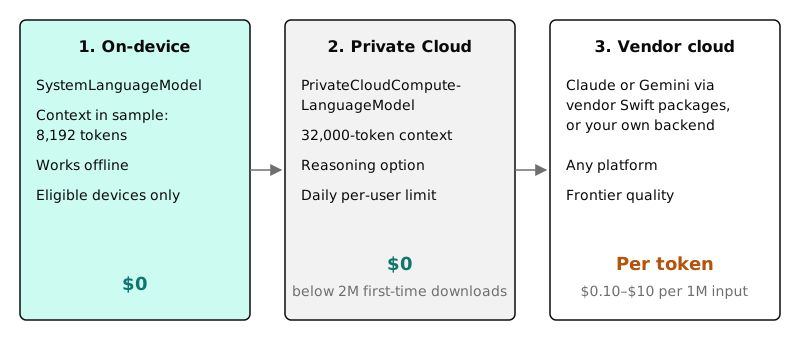
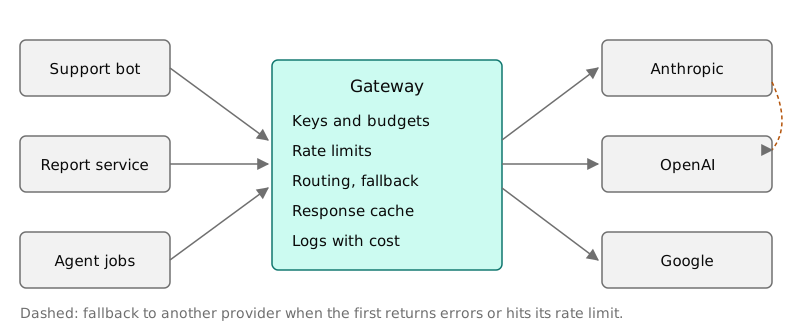
Small Language Models: When a Small Model Is Enough What 1–8B models do well, where they fail, and what they cost to run. Local & On-Device AINovember 1, 2026 LLM Prices 2023–2026: How Far Inference Costs Have Fallen A chart of flagship and budget prices by year, and what the trend means for budgets. AI Cost ArchitectureNovember 1, 2026 LLM Costs at High Volume: After a Million Calls a Day Batching, caching, routing, rate limits and when a self-hosted model wins. AI Cost ArchitectureNovember 1, 2026 The Cheapest LLM APIs in 2026, by Task The lowest price per million tokens for chat, coding, extraction and embeddings, and where cheap stops being worth it. Pricing & ModelsOctober 31, 2026 How Much Claude Code Costs per Month Subscription versus API billing, what drives token use, and how to keep a month under budget. AI Developer ToolsOctober 31, 2026 Batch APIs Compared: OpenAI, Anthropic and Gemini Discounts, limits, turnaround and which workloads fit a batch queue. AI Developer ToolsOctober 31, 2026 The Real Cost of LLM Inference in 2026, Line by Line What LLM inference costs per request in October 2026 for GPT-6, Claude 5.5, Gemini, DeepSeek and Llama, and why output tokens cost 3–8x more. AI Cost ArchitectureUpdated October 31, 2026 The Most Cost-Efficient AI Coding IDE in 2026 October 2026 plans and limits for Cursor, Claude Code, Codex, GitHub Copilot and Gemini CLI, and which one fits how you code. AI Developer ToolsUpdated October 31, 2026 The Hidden Token Tax: Why AI Agents Cost More Than Expected One support ticket can mean five LLM calls and 22,000 input tokens. Worked October 2026 math on why agents cost more than the demo suggests. AI Cost ArchitectureUpdated October 31, 2026 The Best AI Cost Control Tools in 2026: FinOps for LLMs A practical comparison of Helicone, LangSmith, PromptLayer, Portkey, Phoenix, and OpenLLMetry for tracking and controlling LLM costs in production. Inference OptimizationUpdated October 31, 2026 Prompt Caching in 2026: How to Cut LLM Input Costs Prompt caching bills repeated input at 2–10% of the normal price on current models, if static content comes first. How it works per vendor. Inference OptimizationUpdated October 31, 2026 Model Routing: Cut AI Costs Without Losing Quality A routing layer sends simple queries to a small model and hard ones to a flagship. How to build one, and what it saves at October 2026 prices. AI Cost ArchitectureUpdated October 31, 2026 Local vs Cloud AI: The Honest 2026 Cost Comparison One RTX 5090 breaks even with frontier APIs under 1M tokens a day, but needs 17M+ to beat GPT-6 Luna or hosted Llama. Worked numbers, October 2026. Local & On-Device AIUpdated October 31, 2026 How to Use Local Models to Balance AI Costs Run a local model for routine requests and send hard ones to a cloud API: Ollama and LiteLLM setup, routing code and the October 2026 cost math. Local & On-Device AIUpdated October 31, 2026 How Not to Overspend with AI Agents: Budget Guardrails Five guardrails that stop agent loops from running up surprise bills: token budgets, iteration caps, model tiers, explicit stops and tool audits. AI Agent Cost ManagementUpdated October 31, 2026 Enterprise AI Tokenomics: Why the Bill Outgrows the Demo Token prices keep falling, yet enterprise AI bills keep growing. The cause is architecture: repeated context, agent loops, no caching, one model for all. AI Cost ArchitectureUpdated October 31, 2026 Apple Intelligence: What On-Device AI Means for Your Bill Apple's on-device model has no token cost, and Private Cloud Compute is free below 2M downloads. What they handle, how to call them, and the cost math. Local & On-Device AIUpdated October 31, 2026 API vs Subscription: Which AI Pricing Model Saves Money The break-even between pay-per-token APIs and flat-rate plans, worked out for ChatGPT, Claude, Copilot and Cursor at October 2026 prices. AI Cost ArchitectureUpdated October 31, 2026 AI Load Balancers: Route and Govern LLM Traffic at Scale LiteLLM, OpenRouter and Portkey each cover a different part of LLM traffic management: routing, failover, budgets and logs. How they compare. Inference OptimizationUpdated October 31, 2026 7 Smart Techniques to Slash LLM Costs in Production Seven techniques for cutting LLM costs after you pick a model, from prompt compression to batching and caching, with worked examples at 2026 prices. Inference OptimizationUpdated October 31, 2026 The AI Model Map 2026: Paid, Free, Large and Small Every model worth knowing in 2026, sorted by size, price and licence, with what each one is good for. Pricing & ModelsOctober 30, 2026 LLM API Pricing, October 2026: Cost per Million Tokens A dated snapshot of input, output, cached and batch prices for OpenAI, Anthropic, Google, DeepSeek and others, with a source link per row. Pricing & ModelsOctober 30, 2026 Free LLM APIs in 2026: Every Free Tier and Its Limits Which providers give free API access, how much, and what you give up. Pricing & ModelsOctober 30, 2026 An LLM Cost Audit: Where the Money Leaks A checklist for finding waste in an LLM pipeline: long prompts, missing cache, wrong model, retries and agents in loops. AI Cost ArchitectureOctober 30, 2026
Overspent on LLM tokens worldwide
since you opened this page:
$0.00